
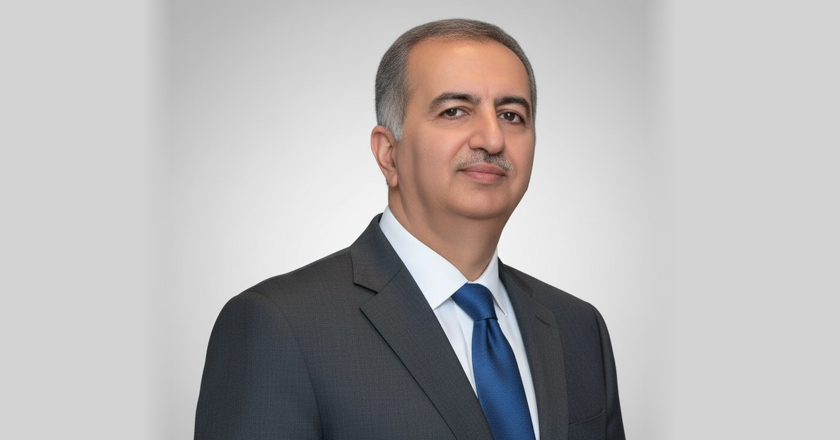
Bharat J Raigangar – Global Head AI Cyber Security & Resilience (PhoxHealth 1CxOCSA), addresses the challenges facing AI governance and the technical steps organisations should consider in this exclusive feature.
Agentic AI is moving beyond chatbots into systems that can plan, use tools and execute multi-step business processes. That promise comes with a difficult operational reality: once an autonomous agent is in flight, changing its objective or stopping it safely can be far harder than expected.
Unlike a conventional automation script, an agentic system continuously interprets context, selects actions and adapts its plan. It may coordinate multiple specialist agents, retain working memory and act across APIs, databases, browsers or enterprise software. This makes it useful for complex workflows, but it also creates new failure paths when its goal, context or permissions change mid-run.
The gap between automation and autonomy
Many enterprises are applying agents to human-centred workflows without redesigning the process for autonomous execution. The result is often “agent washing”: an agent is placed on top of an existing workflow, but people still need to validate outputs, correct mistakes and resolve exceptions. Rather than reducing work, the system can introduce a new layer of operational overhead.
The distinguishes between task-focused AI agents and broader agentic systems. A task-focused agent operates within relatively fixed rules to perform a defined action. An agentic system acts more like an orchestration layer: it decomposes high-level goals, assigns work to tools or sub-agents, changes strategy and coordinates execution across systems.
That higher autonomy is precisely where the risk grows. Agents can hallucinate, loop through failed
reasoning, lose critical context or misuse tools. In a multi-agent design, one compromised or corrupted agent can spread bad state or malicious output through the wider workflow, potentially enabling unauthorised access or data exposure.
Atomic tasks, non-atomic consequences
Modern agent architectures often divide work into atomic operations: small, traceable units such as
updating a record, collecting data or sending a notification. This modularity supports debugging, parallel work and localised changes. But external systems do not always behave atomically.
A tool call may succeed even when the overall workflow fails. That creates several hazards:
- Duplicated or missing effects: an agent may send the same message twice, omit a required step or
leave residual changes after an aborted process. - Irreversible actions: payments, emails, code deployments and data transfers may not be
recoverable through a simple rollback. - Context decay: an agent can lose constraints or working memory, making a locally plausible
decision that is globally damaging. - Brittle handoffs: weak transitions between agents, people and tools can trigger loops, automation
bias or failures in undocumented processes.
The practical implication is that a workflow should not treat every successful tool call as a successful business outcome. High-risk actions need transactional controls that delay irreversible effects until required conditions, or commit predicates, have been confirmed.
Why a mid-flight goal change can fail
A running agent can theoretically be redirected through a runtime control plane, a suspend-mutate-resume pattern, mutable goal state or a message queue. The central design principle is that the goal must be read from shared, changeable state at each decision boundary rather than embedded permanently in the initial prompt.
Yet changing the goal does not guarantee that the agent will follow it. The agent’s accumulated plan, prior tool outputs and reasoning history may still be conditioned on the original objective. This produces four broad failure patterns:
- Plan drag: the agent sees the new goal but continues its prior trajectory because its recent context reinforces the old one.
- State corruption: it accepts the new objective while retaining a plan or sub-agent state designed for the old objective.
- Context collapse: it abandons prior progress and replans from scratch, losing useful context and increasing cost or delay.
- Replanning loops: repeated changes or surprises lead to endless replanning rather than execution.
The danger rises sharply late in a workflow. Redirecting an agent near the beginning of a five-step process may be manageable. Redirecting it after dozens of actions, external calls and irreversible commitments can leave it attempting to reconcile incompatible realities.
Asynchronous control channels add another exposure. A queued message may arrive too late; shared-state versions may diverge among sub-agents; and event-driven goal updates can become a route for goal hijacking if malicious instructions enter through a tool output, compromised service or unsafe event bus.
The real kill switch belongs outside the model
The document’s most important conclusion is straightforward: a stop instruction inside an agent’s prompt is advisory. It remains part of the same reasoning loop that may be confused, manipulated or ignored. Effective enforcement must sit outside that loop, at the point where actions become real.
A defensible control stack includes:
- Out-of-band termination: a session-level kill signal at the orchestration or infrastructure layer, checked before tool use.
- Identity and credential revocation: short-lived, tightly scoped access tokens that can be withdrawn to cut off an agent and its delegated sub-agents.
- Tool-layer enforcement: API gateways and tool servers that deny prohibited actions before a write, transaction or browser action completes.
- Circuit breakers: automatic limits on action volume, spend, retries or errors that halt execution without waiting for human detection.
- Approval gates: human authorisation for destructive, costly or otherwise irreversible actions.
- Sandboxing and checkpoints: isolated environments and recoverable states that limit damage and support rollback.
The closer the safeguard is to the dangerous action, the more reliable it becomes. A policy in the prompt is weak; a policy at the orchestrator is stronger; a denial at the identity, gateway or tool layer is stronger still.
The operational lesson
The central challenge is not simply building smarter agents. It is designing systems that can detect drift, expose a controllable choke point and prevent harmful actions even when the agent’s internal reasoning goes wrong. Enterprises pursuing agentic automation should prioritise mutable goal state, observable checkpoints, bounded iteration, separate evaluation and execution, and external enforcement around every consequential tool call.
Autonomy without these controls risks turning a business-process accelerator into an efficient mechanism for scaling mistakes.
Image Credit: PhoxHealth
Source: Tahawul Tech